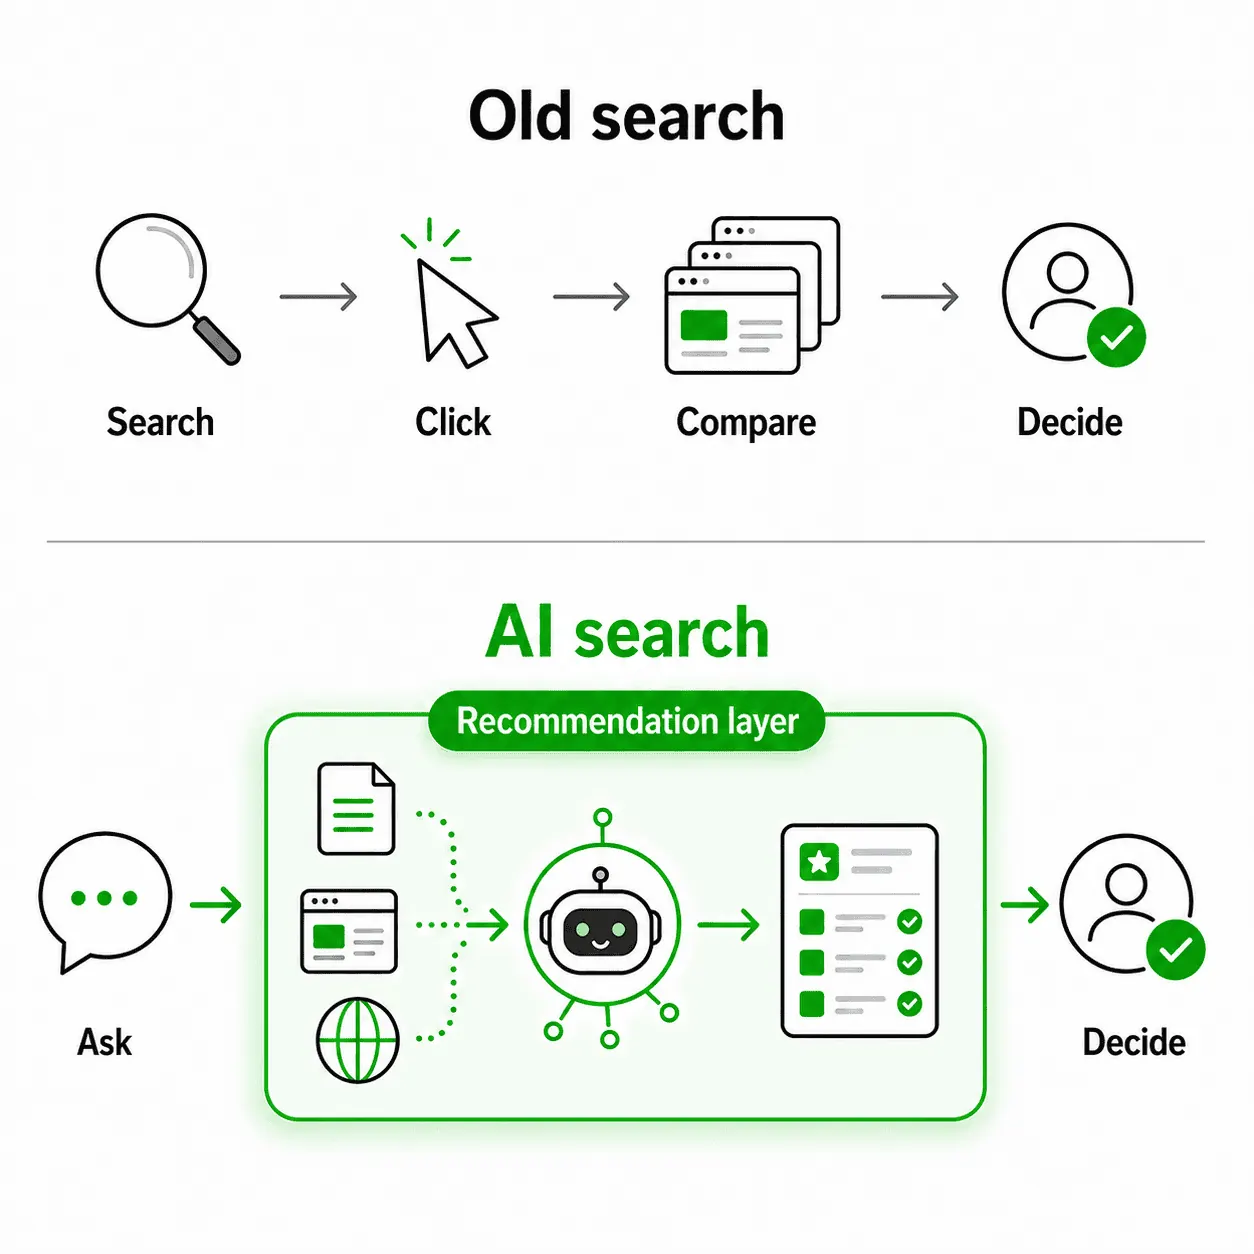
Picture someone buying an espresso machine. Five years ago they typed "best espresso machine under $500," opened six tabs, and argued with themselves for a week before deciding. Now they ask ChatGPT and get three machines ranked with reasons, because the model has already read the reviews, compared the specs, and made the call for them. In Orbit Media's March 2026 survey of 1.1K US adults, 55 percent said AI chat was their primary or frequent tool for research.
Most posts skip this part. That same survey found Google usage hasn't declined, which means this is an addition story more than a replacement story. The shift is what people have always done when choice gets overwhelming: they borrow judgment from something they trust, and the trusted something just stopped being human. A new decision-maker showed up between your customer and your website, and it never scrolls, never gets bored, and has never once been charmed by a hero image.
That new reader is the problem I spend my working weeks on. I build AI visibility systems for enterprise brands, and this post is the mental model behind the work I publish at haydenschuster.com: what the recommendation layer is, how it behaves differently on every surface, and the loop I use to win it. And instead of hypotheticals, I'm going to show you the receipts.
An independent fan reference
I built and maintain this independent fan reference, where I test ideas first. In the archived October 7 Bing AI Performance export, a release-status question drew 6.7K citations at a 47.59 percent citation share. A related navigation guide appeared in the page citation report too. Those are separate reports. One shows what the AI searched for; the other shows which page Bing cited. Put them together and the next page idea is less of a guess. I paraphrase the query and withhold the project name to protect its identity.
Who makes the decision now?
The searching didn't change much. The deciding changed completely.
| Step | Classic search | AI search |
|---|---|---|
| Scans the options | You | The model |
| Compares them | You | The model |
| Judges trust | You | The model |
| Makes the call | You | The model |
| Checks out | You | Increasingly, the agent |
| Visits your site | Everyone | Almost no one |
Every row in that table used to be your customer's job. Search Engine Land calls this territory the AI decision layer, where AI weighs trust, relevance, and authority before deciding who makes the shortlist, and losing here means the customer never learns you existed.
The checkout row is the newest and, for ecommerce, the biggest. Google introduced the Universal Commerce Protocol in January 2026 with Shopify, Target, Walmart and other partners. In May, it announced Universal Cart checkout with Google Pay and Merchant Center AI performance insights, with the checkout features and reporting rolling out rather than available to every merchant at once. The direction is clear: when a shopper can buy from an AI answer, inclusion affects more than a click.
What is the recommendation layer?
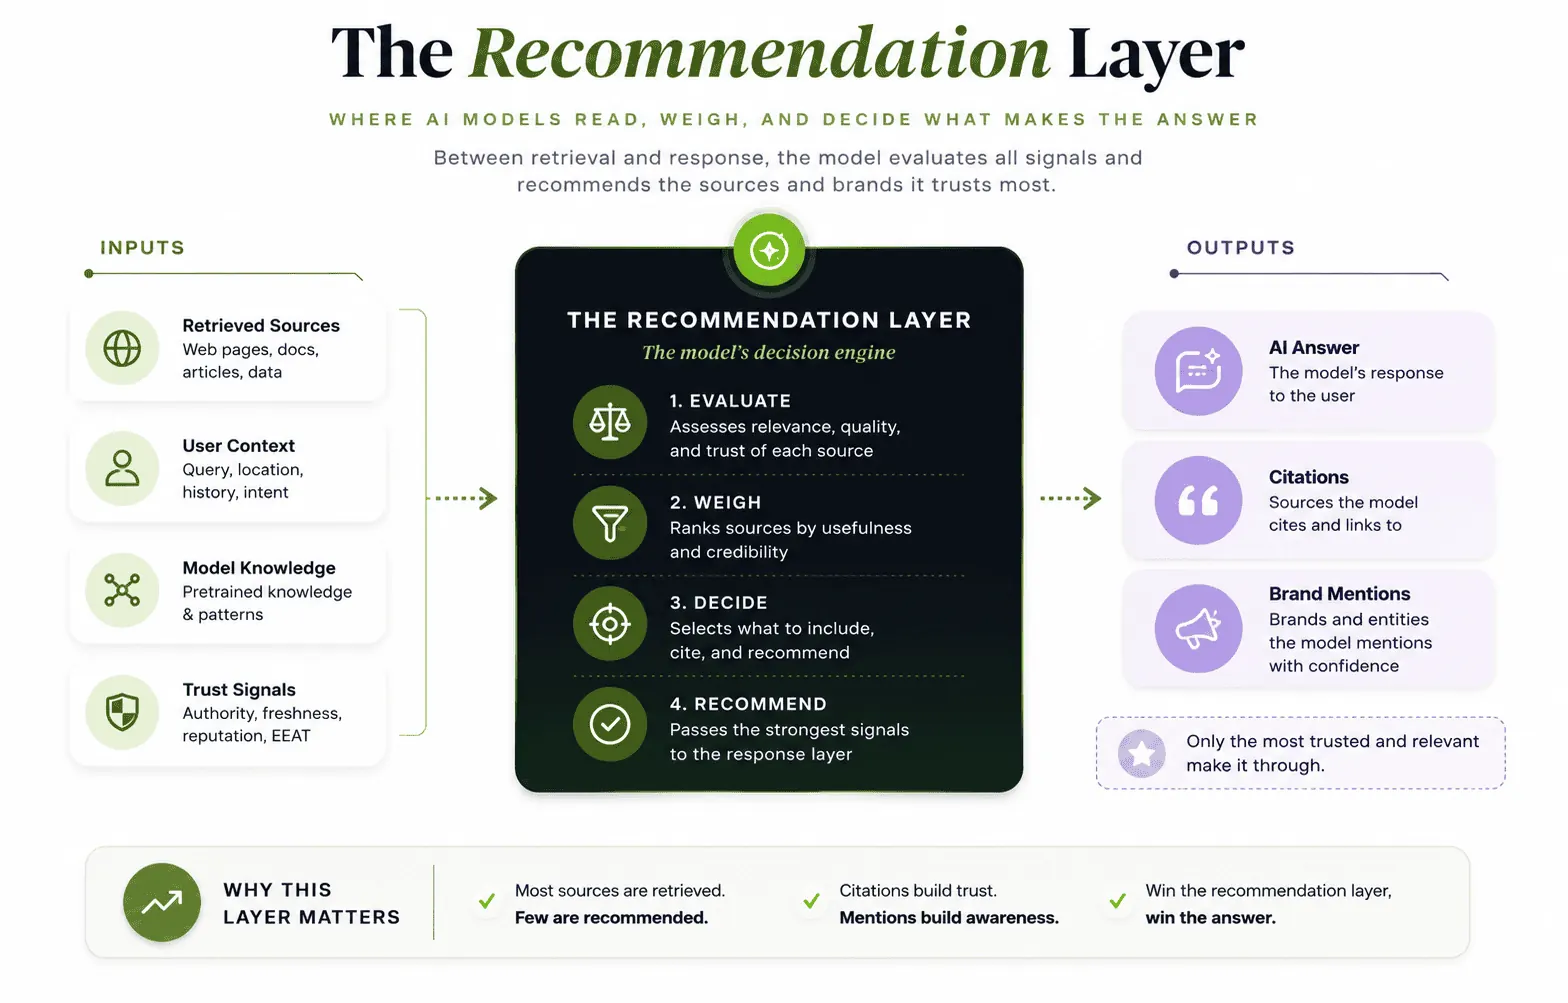
The recommendation layer is the space between a person's question and the answer an AI gives them. It's where ChatGPT, Gemini, Perplexity, Copilot, and Google's AI Mode fetch sources, weigh them, and choose which brands and pages get into the answer. In classic search your job ended at ranking, but here ranking is only the audition, and getting chosen is the job.
If you think your rankings have this covered, they don't. Ahrefs tested 15K prompts and found only 12 percent of links cited by ChatGPT, Gemini, and Copilot rank in Google's top 10 for the same prompt, and around 80 percent do not rank in Google's top 100 for the original query. Your rank tracker is watching one store while the model shops in several.
Fan reference data: the decoupling, live
One question shows the split. In Bing's AI answers, my fan reference holds 68 percent of the citations for a series-navigation query (query paraphrased to protect the project; Bing AI Performance, data through August 26, 2026). A related guide addresses that question. No rank tracker would show the citation share. Read Search Console for search demand, Bing's AI report for citations, and the answer itself for context. One scoreboard is not the whole game.
One layer, five landscapes
"AI search" isn't one thing. Each surface retrieves differently, trusts differently, and rewards different work, and treating them as one blob is how teams end up optimizing for none of them.
| Surface | What it is | What we can verify | What to do |
|---|---|---|---|
| AI Overviews | Google's summary above results on some queries. | Google says it uses Search ranking and index systems; an Ahrefs study found about 76 percent of cited URLs in Google's top 10. | Keep the answer clear on the page, earn the ranking, then check the overview itself. |
| AI Mode | Google's conversational search experience. | Google describes related-query fan-out using its Search index. | Follow the real questions past the head term. Answer the useful follow-ups where they belong. |
| ChatGPT, Gemini and Claude | Assistants people ask directly. | Their web retrieval differs and changes. OpenAI documents OAI-SearchBot for ChatGPT search results; Anthropic documents Claude's web search without naming a permanent index provider. | Test the questions, inspect the citations, and make sure documented crawlers can reach the source. |
| Copilot | Microsoft's assistant across its products. | Bing Webmaster Tools reports citations across Copilot, Bing AI answers and select partners; its grounding queries are a sample. | Read the cited URLs and question patterns. Citation count is not a ranking position. |
| Perplexity | An answer engine that cites sources. | Perplexity describes its crawler and indexing fleet; Ahrefs found about one in three citations in Google's top 10 for the same prompt. | Keep the source reachable; look at the pages it actually cites. |


The overlap figures in that table are Ahrefs data, and the spread is the point. AI Overviews cited Google's top-ranking pages much more often than the assistants in that study. But citation overlap does not reveal each provider's internal plumbing. Build for access, evidence and a good answer; then read the actual citations. One ranking report cannot speak for five surfaces.
Fan reference data: a fan-out in the wild
Bing's grounding-query export for the fan reference includes many phrasings of when the next book arrives. A single head keyword hides those follow-up questions. The variants are the outline: check whether the release-date page answers each form the AI searched for. I paraphrase the questions to keep the project unnamed.
A mention is not a citation
A mention is the model saying your name, while a citation is the model pointing at your content as the source. Here's the shape of each, using a real page from CheckMyTap, one of my sites.
Mention: a name or category without a source link
"Several independent sites publish city-level water quality data."
This illustrative answer names a category but gives no source link. That output alone does not show whether the information came from training data, retrieved pages or another source.
Citation: the model using your evidence
"CheckMyTap's Phoenix page lists the city's measured hardness, lead, and PFAS readings [checkmytap.com]."
This illustrative citation gives a reader a page to inspect. I still need to open it and check that the readings support the answer; the link itself does not establish accuracy.
Most brands celebrate the first one and stop. Screenshots are not a strategy, and the two don't reliably travel together:
62% of AI citations are "ghost citations": the AI links a site as a source but never says the brand's name, per Kevin Indig and Semrush's analysis of 4K domain appearances across ChatGPT, Gemini, AI Overviews, and AI Mode.
I track a brand mention and a source citation separately. A recommendation can name a brand without linking its own content, and a page can be cited without naming its publisher in the answer. Neither pattern tells me why the model selected it.
The three checks I use on a page
Accuracy note, October 30, 2026: these are my review checks, not universal model requirements. OpenAI says search responses may include citations, and Google distinguishes eligibility for supporting links from guaranteed inclusion. A citation still needs to be checked against its source.
I use three practical checks alongside Found, Understood, Chosen: can the page be retrieved, can a reader check its claims, and does an answer make sense when quoted?
I check the claims behind an answer

1. Visibility: can I even get to this?
Visibility means the model can reach and retrieve your content when it goes looking, which makes it a question about retrieval rather than rankings. If robots.txt blocks AI crawlers they can't read you, and if your words only appear after scripts load, some systems see an empty page, which is why my technical foundations work starts with what survives a raw crawl. The model also doesn't limit itself to your site; it leans on the places it already trusts, like review platforms, forums, Reddit, and YouTube, so sometimes the fastest win isn't on your domain at all.
Pass it when AI crawlers are allowed on purpose, your key content lives in the raw page code, and you show up on the third-party sources models pull from in your category.
Fan reference data: passing visibility
Every page ships as plain, static HTML, so nothing important waits on JavaScript, and robots.txt is open on purpose rather than by accident. Each meaningful deploy pings Bing through IndexNow, a fast way of telling Bing a page changed. That gives Bing a fresh URL to crawl; it does not guarantee a citation in Copilot or any other assistant.
2. Verifiability: can I trust this enough to repeat it?
Verifiability means a reader can trace a claim to evidence. I want an answer to point at something that can be checked, including data I assembled myself. That is a publishing standard I can enforce; it does not mean a model verifies every claim before repeating it. It's why CheckMyTap opens every city page with that city's actual readings, and why modern search systems need consistent, checkable facts about who you are everywhere they look. The original GEO research from Princeton, Georgia Tech, and IIT Delhi found that citing credible sources inside your own content was a top tactic for AI visibility, which is worth reading twice: citing others makes you more citable.
Pass it when claims link to named sources, content carries a real byline instead of "admin," and your site, profiles, and listings all agree on who you are.
Fan reference data: passing verifiability
Structured data (machine-readable labels for the series, the books, and the author) ties every fact to sources like Wikipedia and Goodreads, so the page presents one consistent set of source relationships. The build enforces honesty too: an automated check fails the deploy if a stale fact leaks into a page, and in the last content review, five proposed pages were killed because their facts couldn't be verified against a primary source. Those checks catch known mistakes; they do not prove every remaining claim is correct.
3. Quotability: can I lift a clean answer out of this?
Quotability means one of your sentences still makes sense when lifted into an answer. The Princeton-led GEO study built a 10K-query benchmark and evaluated tactics on its 1K-query test split. In its experimental answer engine, statistics, quotations and cited sources improved visibility, with the best result near 40 percent on one measure; keyword stuffing did little. Your customers have written quotable material too. A review with a name and a specific experience can say more than a line of marketing copy. The difference is easier to see than explain:
What most pages write
In today's competitive landscape, choosing the right solution can feel overwhelming, which is why it's important to consider a variety of factors.
What machines quote: a real line from this post
Only 12 percent of links cited by ChatGPT, Gemini, and Copilot rank in Google's top 10 for the same prompt.
Pass it when every section opens with a complete, specific, standalone claim, which is the whole idea behind answer-first structure. The first sentence above contains zero facts a model could repeat; the second gives the reader a sourced finding they can check.
Fan reference data: passing quotability
Each reference page opens with the current answer, its definition and its source in one liftable passage. FAQ answers stand alone, and one FAQ earned 695 Google clicks in three months. The split shows up in the data too: an interactive tool won clicks (a 16.6 percent click rate, visitors averaging two-plus minutes), while reference pages won citations. Build both, and know which prize each one is chasing.
What the research says works
The GEO paper (Aggarwal et al., KDD 2024) evaluated content tactics on a 1K-query test split of its 10K-query benchmark. In that experimental setting, adding verifiable detail and quotations improved its visibility measures.
| Tactic | In practice | Result |
|---|---|---|
| Add statistics | Specific numbers over vague claims. "Removes 99 percent" beats "highly effective." | Among the biggest gains tested |
| Cite sources | Link claims to named, credible references inside the content. | Top performer, biggest lift for lower-ranked pages |
| Add quotations | Quote named experts directly, with attribution. | Strong, consistent lift |
| Keyword stuffing | Cramming the phrase in over and over. The old playbook. | Made visibility worse |
| Persuasive fluff | Confident marketing language with nothing checkable behind it. | No meaningful gain |
Notice what this post is doing. The answer sits at the top, every stat names its source, and the highlighted sentences are the ones a machine could lift whole. Those are the same checks I use when reviewing this post.
GEO is SEO
Time to kill the laziest myth in the industry while we're here.
Look back at everything above and notice what it's made of. Crawlability and rendering are technical SEO. Entities, structured data, and consistent facts are the understanding layer SEO has been building for a decade. Answer-first content matched to real intent is what good SEO content always was, and it's the whole reason Found, Understood, Chosen maps onto this so cleanly. GEO is SEO. The fundamentals didn't change; the judge did. So no, SEO is not dying. It has never been more essential, because the machine now reads everything before your customer reads anything, and the discipline that decides what machines find, understand, and choose is the one this industry has been practicing all along.
What did change is that it stopped being a solo sport. The models lean on Reddit threads, reviews, and YouTube, which is social and community's turf. Retrieval depends on rendering, structured data, and index pings, which is the developers' turf. The moat data comes from strategy and product, and the measurement loop touches analytics. The brands winning this run SEO as a cross-functional system rather than a department, because a shared roadmap helps the teams publish consistent, checkable information. The machines will answer either way. The question is whether they answer from verified sources or from noise, and making sure it's the former is the job. That's why this work matters more now, not less.
The loop I run on my own sites
On my own sites, the work settles into the same four-beat loop, and it works at any size.
Listen. Run the real questions buyers ask, on a schedule, across ChatGPT, Gemini, Perplexity, and Google's AI surfaces, and track two things separately: whether the brand is in the answer, and whether the brand's own content is the source. Open the sources behind each answer to see which accounts of the brand are represented.
Mine. The dashboards are a content calendar wearing a scorecard costume. Every question, sub-search, and grounding query the brand hasn't directly answered becomes a brief.
Answer. Rewrite the pages that matter so each section opens with the answer, turn the mined sub-questions into FAQ entries that actually resolve them, and publish the moat data only this brand has.
Verify. Watch mentions and citations separately on each surface over the following weeks. If they move differently, inspect the actual answers, cited pages and prompts before deciding what to change. A citation increase does not prove trust, and a mention without a citation does not establish a lack of evidence. Use the split to choose the next investigation, then test the proposed change.
Every green box in this post is that loop running on my own hobby site, with Bing's grounding report as the citation scoreboard. The Quack Report runs the same playbook on Oregon football history, keeping every rivalry record and season result at its own citable address, and CheckMyTap runs it on city water data. The subjects have nothing in common, and I use the same review checks on each.
Your dashboards are a content strategy
Most teams read these four tools as report cards, but the better read is that each one hands you the next thing to write. It helps to know why measurement is hard in the first place: someone asks ChatGPT, gets your brand, then googles your name, and your analytics logs a branded search. The AI's fingerprints are nowhere in the data, so you triangulate.
Peec AI: what to answer next
Feed Peec AI your buyer questions and it runs them across ChatGPT, Perplexity, Gemini, and Google's AI surfaces on a schedule, tracking whether you appear, how you're framed, and which sources shaped each answer, and it exposes the fan-out queries behind each one.
The move: Those fan-outs and tracked questions are a ready-made FAQ outline. Answer each one directly on your site and you're covering demand your keyword tools will never show you.
Blind spot: The answers come from scheduled test prompts, not real people's sessions. Since September 11, 2026 Peec can also pull AI referral visits from Google Analytics, but those show the click by assistant and landing page, not the question that led to it.
Bing Webmaster Tools: what retrieval already likes
Microsoft's AI Performance report, introduced in February 2026, shows page-level citations across Copilot, Bing AI answers and select partners, plus a sample of grounding queries. It's a free look at where pages were cited and what the system was trying to answer, and it's the source of the citation numbers in this post. Since June 16, 2026 it also sorts those queries by intent and by topic, shows each site's share of the citations for a query, and lays one period over another; since October 13 a Topics Portfolio beta lists the queries in each topic where other sites are cited and yours isn't.
The move: Treat grounding queries as briefs. Read the cited page and the question together, then improve the answer or build the missing page. Test ChatGPT separately; Bing citations do not tell you which sources ChatGPT used.
Blind spot: Microsoft's ecosystem only. No click data yet.
Google Search Console: how people phrase it now
Google counts AI Overviews and AI Mode in the standard performance report, and since June 3, 2026 Search Console also gives them a dedicated Generative AI report, open to every site worldwide since August 31 and split by text and image searches since September 24. Read the two together, and read them through patterns. Impressions climbing while clicks stay flat deserve an investigation, not an instant AI win label: inspect the queries and live results. On the fan site, one character page pulled 87.9K impressions in three months at a 0.35 percent click rate. That proves demand and thin click-through; the result page tells you where the answer went. My approach to using GSC as a visibility dashboard matters more now, not less.
The move: Mine the query report for the longer, question-shaped queries showing up against each template. Those are prompts in disguise, and they track exactly how search behavior is shifting. Give every one a direct on-page answer.
Blind spot: The Generative AI export I pull has impressions, not clicks, so what happened after the answer is still an inference.
GA4: which pages convert the machine's clicks
GA4 added an AI Assistant channel in May 2026. It groups recognized assistant referrers; Google's channel definition excludes AI Overviews and AI Mode, so I still inspect session sources and use a custom group when I want to include more referrers. On the fan site, the AI channel catches about a hundred sessions a month (155 in the 30 days to July 17), which is real but a fraction of what the citation data shows upstream. Seer Interactive's single-client case study measured ChatGPT referrals converting at 15.9 percent against 1.76 percent for Google organic from October 2024 through April 2025. That comparison describes one client and one period; it does not predict the conversion rate for another site.
The move: Run landing page by AI source. The pages already earning AI clicks and conversions are your template, so make the rest of the site look like them.
Blind spot: Undercounts hard. Many AI visits arrive with no referrer and get logged as Direct.
Bringing it together: the build sheet
Here is how I turn those checks into page work and choose what to inspect first.
| My check | What you actually build | Evidence to inspect |
|---|---|---|
| Visibility | Open crawler access, key content in the raw page code, and presence on the review sites, forums, and channels models already trust in your category. | A crawl with scripts off, Bing's cited-URL gaps, and Peec's source lists showing which domains shape your category's answers. |
| Verifiability | Moat data: the readings, pricing, and test results only you have. Plus consistent brand facts everywhere and real bylines on everything. | Peec's framing and source reports. If the model describes you from someone else's words, that page is the P1. |
| Quotability | Answer-first openers, real review pull quotes with attribution and markup, spec tables in plain HTML, and FAQ entries built from fan-outs. | Fan-out queries, GSC's question-shaped queries, and Bing's grounding queries: the exact sentences to write next. |
What I look for in the fan reference data
A grounding query can show an answer drawing on a nearby page while the site has no dedicated answer. Check the cited URL, the question and the page. If the gap is real, move the answer up the build queue. The report shows what was cited, not why Bing chose it.
That's the priority rule, and it holds on every site of mine, whatever the topic: P1 is wherever a surface already wants you but can't use you. That means grounding events that never become citations, mentions that never come with citations, and questions sitting in your own data that nothing on your site answers. Fix the pull before you build more push. This is the same system behind my modern search portfolio work, just written down.
The companion rule matters just as much: a winner is a map for the next build. When a page starts earning citations, the data clustering around it (the fan-out phrasings, the grounding queries, the question-shaped searches) is the machine handing you the outline for the next FAQ entry, the next post, and the next topic cluster. Prioritize those neighbors and double down, because the surface has already voted, and expanding a proven winner beats guessing at a new one every time. On my independent fan reference, the release-answer page connects to navigation, recap and installment pages. Each answers a different reader question, and the citation data shows where those questions overlap. Gaps tell you where to start. Winners tell you where to build.
Where do you start?
In this order, because each step is cheap and each one makes the next one smarter.
- Run your own answers, manually, today. Put your 20 real buyer questions through ChatGPT, Gemini, and Perplexity and screenshot everything, which gives you a free baseline showing whether you're mentioned, cited, both, or invisible.
- Check that the machines can reach you. Review robots.txt for AI crawler rules you didn't know you had, and load key pages with scripts off. If the content disappears, so do you.
- Rewrite your most important pages answer first. Open every section with one standalone, specific sentence, and put a number in it wherever the truth allows one.
- Make yourself checkable. Link claims to sources, put real names on content, and make every description of your brand agree with itself.
- Then build the stack and run the loop. Use Peec for answers, Bing for citations, GSC for phrasing, and GA4 for the money end, and run the loop: listen, mine, answer, verify.
What decides who AI recommends
The decision moved. People still search, but AI answers now help them read and compare before they reach a site. The surfaces behave differently: Google's AI Overviews overlap heavily with top results in Ahrefs' study, while Google's AI Mode can fan out into related queries. The assistants need their own citation checks. With agentic checkout rolling out through UCP and Universal Cart, the answer is starting to double as the store shelf.
Being named and being cited are different observable outcomes. I measure both, then read the answers and sources before interpreting the difference.
My three checks give me a place to start: whether the page can be reached, its claims can be checked, and its answer can be quoted clearly. GEO is SEO pointed at a new judge, your dashboards hand you the roadmap when you read them as inputs instead of report cards, P1 is wherever a surface already wants you but can't use you, and every win maps the next one. Bing's October export counted 6.7K citations against one forthcoming-book release-date question on my independently owned fan reference. The excuse shelf is empty.
The ten blue links gave everyone a shot, but the recommendation layer only has room for the sources it trusts. Be one of them.
First published on my old site July 18, 2026 and moved here October 11, 2026.